Democratizing Massive Model Training
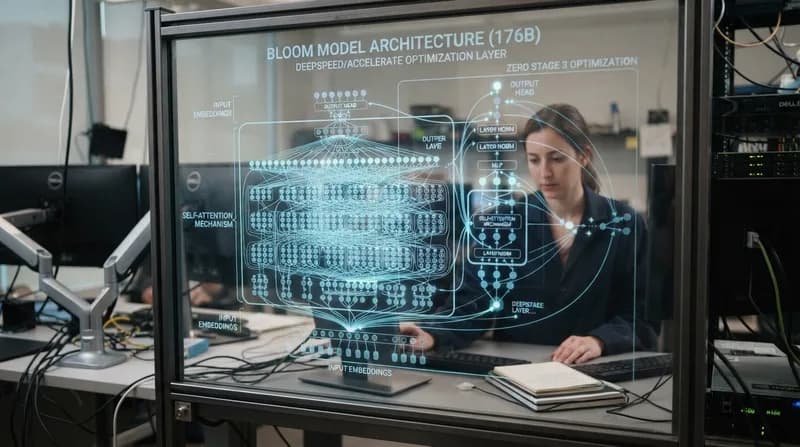
Training and deploying models that reach the scale of 176 billion parameters, such as the BLOOM architecture, has traditionally been reserved for organizations with bottomless infrastructure budgets. However, Hugging Face is bridging this gap through its Accelerate library. By leveraging the power of PyTorch, the platform provides a robust framework that simplifies the complexities of running ultra-large models across distributed hardware setups.
The Accelerate ecosystem focuses on abstracting the hardware-heavy lifting. It allows researchers to transition from a single GPU environment to massive clusters with minimal code changes. This efficiency is critical for maintaining performance parity when shifting from local development to the massive parallel processing required by models of this caliber.
Why it matters
- Resource Efficiency: By optimizing memory usage and distributed communication, Accelerate lowers the barrier for academic and independent research groups.
- Seamless Integration: It maintains full compatibility with native PyTorch training loops, ensuring developers don't have to rewrite entire codebases to scale.
- Model Performance: Fine-tuned resource management ensures that massive parameter sets remain stable, reducing the likelihood of gradient overflow or synchronization bottlenecks during high-intensity compute cycles.
The Future of Model Accessibility
The success of the 176B-parameter BLOOM model serves as a proof-of-concept for the Accelerate library. By enabling seamless distributed inference and training, Hugging Face is fundamentally changing how the open-source community interacts with foundation models. As these models continue to grow in complexity, the role of orchestration tools becomes even more vital, ensuring that the hardware can keep pace with the ambitions of AI researchers globally. By stripping away the technical friction of distributed computing, the industry is moving closer to a future where world-class AI capability is determined by data quality and ingenuity rather than pure access to proprietary hardware stacks.