Breaking Through Inference Barriers
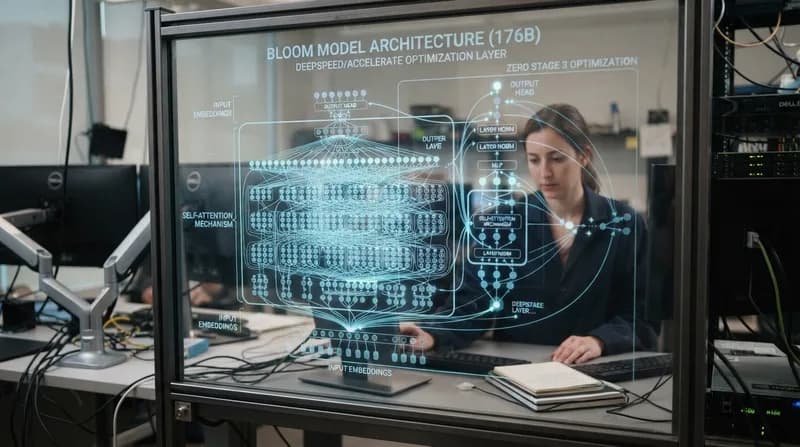
Running a massive 176-billion parameter model like BLOOM has long been a significant challenge for researchers and developers. Due to the immense memory requirements of such large-scale language models, deploying them typically necessitated costly, high-end infrastructure that remained out of reach for many smaller teams. However, new technical implementations from Hugging Face, utilizing Microsoft's DeepSpeed and the Accelerate library, are drastically lowering the barrier to entry for local and cloud-based inference.
By leveraging tensor parallelism, the updated scripts allow for the distribution of model weights across multiple GPUs. This architectural shift enables the model to fit into memory by splitting the load, effectively making high-performance generation possible on hardware that would otherwise be insufficient for a singular, massive model deployment.
Why it Matters
- Reduced Latency: Optimized kernel integration results in significantly faster tokens-per-second generation.
- Accessible Compute: Enables the operation of massive models on more standard multi-GPU server configurations.
- Scalability: Provides a standardized framework for developers to deploy large-scale LLMs without needing custom-built infrastructure.
The synergy between DeepSpeed’s ZeRO-Inference technology and Hugging Face’s Accelerate library ensures that model weights can be loaded and processed with minimal overhead. This breakthrough isn't just about speed; it is about democratizing access to state-of-the-art AI. By providing these scripts, the community can now move beyond theoretical research and into practical, performant applications for massive models. This integration represents a major milestone in the move toward more efficient, hardware-aware AI deployment, ensuring that the next generation of foundation models can run reliably in diverse environments.