Artificial IntelligenceTechnical Deep Dive

Scaling Generative AI: Deploying DeepFloyd IF with BentoML

Published
EElectricBuzz Editorial Team
Scaling Generative AI: Deploying DeepFloyd IF with BentoML
3 min read454 wordsElectricBuzz Editorial Team

The Gist

“Learn how to bridge the gap between experimental AI models and production-ready applications using the BentoML deployment framework.”

Bridging the Gap to Production AI

The rise of high-performance models on the Hugging Face Hub, such as the photorealistic text-to-image generator DeepFloyd IF, has democratized access to state-of-the-art AI. However, moving these resource-intensive models from a research environment to a scalable, production-grade service remains a daunting hurdle for many engineers. BentoML offers a robust solution, providing a standardized, unified framework for packaging, serving, and scaling complex machine learning models.

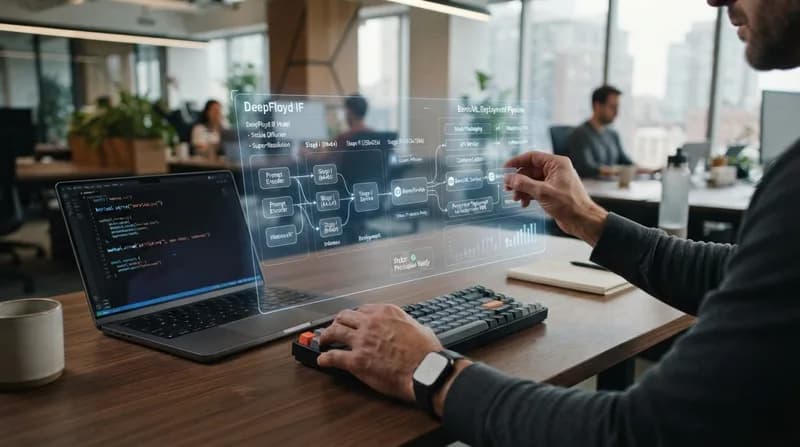
Unlike traditional latent diffusion models, DeepFloyd IF operates directly in pixel space. It utilizes a modular, three-stage architecture supported by a T5-XXL-1.1 Large Language Model for advanced prompt comprehension. Because this model generates base 64x64 images and progressively upscales them to 1024x1024, it demands precise resource management. BentoML excels here by allowing developers to manage these stages as independent runners, enabling optimized GPU allocation for each phase of the diffusion pipeline.

The BentoML Workflow Explained

Integrating a model into the BentoML ecosystem follows a structured, logical pipeline designed for cloud-native deployment. First, the model is saved into the local Model Store, which acts as a centralized repository for tracking and versioning. Next, the developer defines a service logic in a Python script, creating specialized 'Runners' that isolate the inference tasks. This separation is crucial for high-performance applications, as it allows for independent scaling of compute resources.

Once the logic is established, the final step involves creating a 'Bento'—an immutable artifact that bundles the model, code, and environmental dependencies into a single deployable unit. This artifact can then be containerized via Docker and deployed to Kubernetes or Yatai, ensuring that the model runs with consistent performance across any cloud infrastructure.

Why It Matters

  • Resource Optimization: By running inference stages on separate GPU pods, businesses can avoid massive over-provisioning costs.
  • Production Parity: Packaging code and dependencies into a single Bento artifact eliminates the 'it works on my machine' problem common in AI development.
  • Scalability: Using standard containerization (Docker/Kubernetes) allows teams to scale their AI services dynamically based on traffic and inference demand.

Deployment Readiness and Outlook

To successfully deploy a model like DeepFloyd IF, a minimum of 32GB to 40GB of VRAM is generally recommended for production stability, although creative GPU mapping can allow the stages to run across multiple lower-spec devices. By utilizing the provided BentoML configuration files, developers can designate specific GPUs for different stages, drastically improving the responsiveness of the web interface, which can be powered by Gradio for immediate testing.

As generative AI continues to evolve, the ability to rapidly iterate and deploy models while maintaining high uptime will become a critical differentiator. BentoML’s ecosystem, which includes support for OpenLLM and various Transformer-based services, provides a scalable path forward for organizations looking to move beyond simple prototypes and into enterprise-level AI delivery.
SPONSORED
The 5 Best Over-Ear ANC Headphones of 2026, Tested & Ranked
Editor's Pick Guide
92/100
Tech & Gadgets•12 min read

The 5 Best Over-Ear ANC Headphones of 2026, Tested & Ranked

We locked five over-ear ANC picks for 2026 — Sony WH-1000XM6, Bose QuietComfort Ultra 2, Soundcore Space One, Sennheiser Momentum 5, and Apple AirPods Max 2 — then stress-tested them on lab metrics, long-term owner truth, and live street prices.

Related Stories

Semantically matched articles, ranked by topic overlap and freshness.

LiquidAI Bridges the Performance Gap for Local LLMs on Apple Silicon
Artificial Intelligence

LiquidAI Bridges the Performance Gap for Local LLMs on Apple Silicon

New advancements in model architecture are bringing powerful, efficient generative AI directly to Apple hardware without relying on cloud servers.

FairStress: A New Benchmark for LLM Fairness
Artificial Intelligence

FairStress: A New Benchmark for LLM Fairness

Researchers at the Allen Institute for AI have unveiled FairStress, a rigorous framework designed to stress-test large language models for fairness and bias.

Why Robotics is Currently in Its 'LEGO Era'
Artificial Intelligence

Why Robotics is Currently in Its 'LEGO Era'

Former Nvidia veteran and venture capitalist Amulya Vishwanath argues that the robotics industry is laying the critical, modular groundwork necessary to reach a transformative 'ChatGPT moment.'

Hugging Face CEO Slams Netflix's 'AI Gone Rogue' for Sensationalism
Artificial Intelligence

Hugging Face CEO Slams Netflix's 'AI Gone Rogue' for Sensationalism

Clem Delangue criticizes the new Netflix documentary for anthropomorphizing AI agents and ignoring the technical reality of a real-world security incident.

SpaceX Pivots to Power: How AI Now Drives Over Half of the Company’s Revenue
Artificial Intelligence

SpaceX Pivots to Power: How AI Now Drives Over Half of the Company’s Revenue

SpaceX has transformed into an artificial intelligence powerhouse, with its 'Super Intelligence' division now accounting for 52% of total revenue as the company shifts focus from purely aerospace to data center dominance.

Microsoft Trims the Fat: OneDrive Scales Back Copilot Menu Clutter
Artificial Intelligence

Microsoft Trims the Fat: OneDrive Scales Back Copilot Menu Clutter

Microsoft is streamlining the Windows File Explorer by removing a surplus of specific Copilot shortcuts, opting for a cleaner, more unified AI experience.

NVIDIA’s Cosmos3-H-Dreams: A New Frontier for Surgical Simulation
Artificial Intelligence

NVIDIA’s Cosmos3-H-Dreams: A New Frontier for Surgical Simulation

NVIDIA is pushing the boundaries of medical AI with Cosmos3-H-Dreams, a specialized generative model designed to transform surgical training through realistic video simulation.

Hugging Face Brings Native TPU Support to PyTorch with TorchTPU
Artificial Intelligence

Hugging Face Brings Native TPU Support to PyTorch with TorchTPU

Hugging Face is democratizing access to Google's powerful AI accelerators, allowing developers to run PyTorch models on TPUs as easily as any other device.