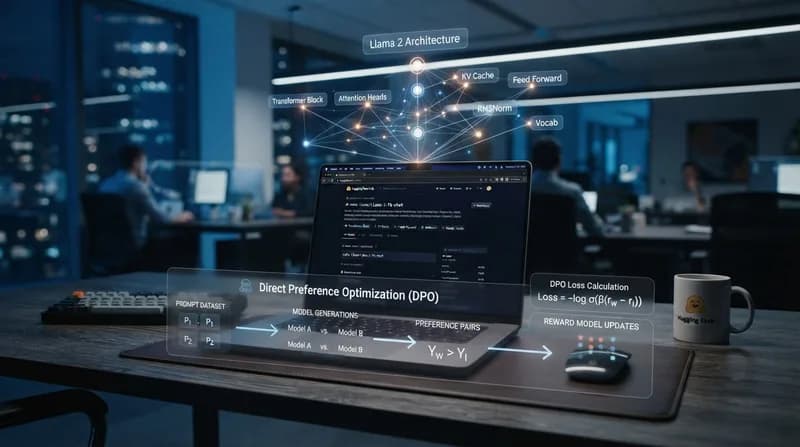
Revolutionizing Model Alignment
The landscape of large language model development has reached a pivotal juncture with the introduction of Direct Preference Optimization (DPO) for Llama 2. Historically, aligning models with human preferences required complex Reinforcement Learning from Human Feedback (RLHF) pipelines, which often involve maintaining multiple models and a separate reward model. By utilizing DPO, developers can now streamline this process, effectively bypassing the need for heavy external infrastructure.
DPO functions by directly optimizing the language model on preference data, such as a dataset containing 'chosen' versus 'rejected' responses. This creates a mathematically stable and computationally efficient bridge between raw model training and human-aligned output. By leveraging the TRL (Transformer Reinforcement Learning) library from Hugging Face, researchers can integrate these advanced alignment techniques into existing workflows with minimal friction.
Why It Matters
- Efficiency: DPO eliminates the requirement for training a separate reward model, significantly lowering the GPU memory footprint.
- Simplicity: It simplifies the training loop, allowing smaller teams to achieve performance levels previously reserved for large-scale enterprise labs.
- Performance: Fine-tuning with preference data leads to models that are more helpful and less likely to generate harmful or hallucinatory content.
Implementation Outlook
The integration of the kashif/stack-llama-2 dataset demonstrates how community-driven data can be harnessed to polish base models. As the open-source community continues to adopt DPO, we expect a rapid surge in the availability of highly tuned Llama 2 variants tailored for specific domains. This shift marks a broader transition in AI development where the emphasis is moving from purely scaling parameters to refining model behavior through sophisticated, accessible optimization methodologies. By lowering the barrier to entry for RL-based alignment, Hugging Face is enabling a new wave of robust, safer AI applications that reflect genuine human interaction patterns rather than just statistical probability. Developers looking to refine their own models now have a blueprint that is both scalable and technically elegant, ensuring that Llama 2 remains a dominant force in the open-source AI ecosystem for the foreseeable future.