The Emergence of Distributed AI Training
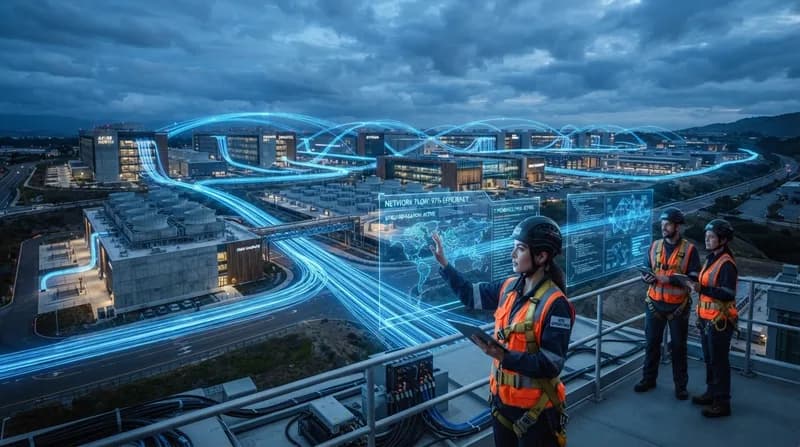
The race to build increasingly massive AI models has hit a physical wall: power availability. With power grids and local infrastructure unable to keep pace with the insatiable energy demands of modern GPU clusters, the era of the 'single-datacenter' training workload is drawing to a close. Industry leaders are now forced to adopt a distributed model, where training clusters are spread across multiple geographically distinct locations.
This transition introduces a profound architectural hurdle. Traditional networking solutions were built to facilitate traffic flow between sites, but AI training requires something fundamentally different. These workloads demand massive, synchronous data transfers with near-zero packet loss and perfect coordination between distributed GPU clusters. If any segment of the network experiences a stall, the synchronization delay can cascade, effectively crippling the entire training job. Consequently, the network is shifting from a passive transport layer to an essential component of the compute fabric itself.
The 'Scale-Across' Imperative
Cisco is tackling this challenge through what it calls the 'Scale-Across' imperative. According to Rakesh Chopra, SVP of Silicon and Systems Architecture, the goal is to make geographically dispersed data centers behave like one singular, deterministic machine. Achieving this level of performance over long-distance fiber links requires more than just raw bandwidth; it demands sophisticated hardware-level integration.
Key to this approach is the evolution of silicon and optical technologies. By utilizing high-speed coherent optics and deeply integrated silicon, engineers can manage the massive, synchronized bursts of traffic inherent to LLM training. Cisco’s strategy emphasizes the use of 'Intelligent Collective Networking,' which is designed to identify and resolve bottlenecks in real-time, drastically reducing job completion times by ensuring that GPUs spend less time waiting for data and more time processing.
Why it Matters: The Networking Bottleneck
- Determinism: AI training relies on synchronized states; even minor latency variations across a network can lead to GPU idle time, costing millions in wasted compute cycles.
- Power Efficiency: As network infrastructure scales, it must be optimized to ensure that energy is directed toward processing rather than overhead, balancing the power budget between compute units and the interconnect fabric.
- Security at Scale: With data crossing long distances, hardware-accelerated security protocols like MACsec and IPsec have become critical to maintaining data integrity without introducing significant latency.
- Programmability: Because AI architectures evolve rapidly, infrastructure must be flexible enough to adapt to new communication patterns without requiring a complete hardware overhaul.
A New Blueprint for Infrastructure
For data center architects, the path forward is clear: the network is no longer a peripheral service; it is the backbone of AI scaling. By leveraging advanced silicon architectures like Cisco's Silicon One, companies are beginning to treat distributed sites as a unified entity. As the industry moves toward this multi-site reality, the ability to manage deterministic, high-speed communication over long distances will define which organizations can successfully train the next generation of foundation models without hitting the physical ceilings of localized power.