The Challenge of GPU Scarcity
In the world of cutting-edge AI research, compute power is the ultimate currency. At the Allen Institute for AI (Ai2), the infrastructure team oversees a massive fleet of NVIDIA H100, B200, and B300 GPUs. With a user base of 150 researchers spanning robotics, reinforcement learning, and large-scale model training, the demand for hardware consistently outstrips supply by a factor of two or three. Historically, managing this scarcity relied on a priority-based scheduler, which led to predictable and damaging behaviors: users engaged in GPU 'squatting' to hold onto resources, and priority inflation meant that almost every job was marked 'HIGH,' effectively rendering the priority system useless.
The Shift to Budget-Based Allocation
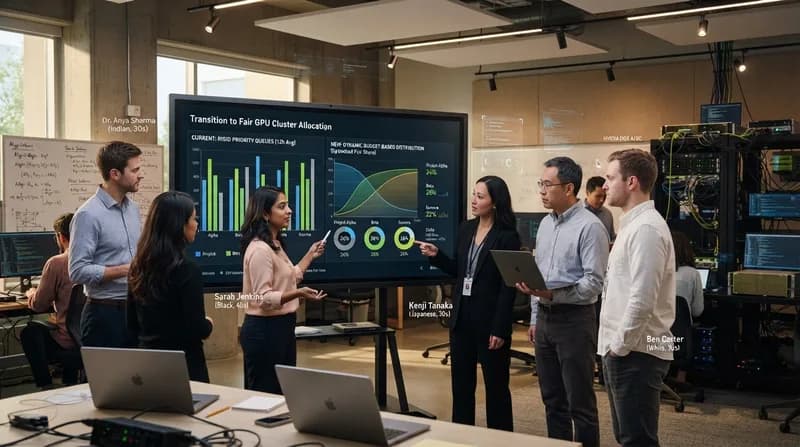
The team at Ai2 realized that they were trapped in a classic 'tragedy of the commons.' To solve this, they moved away from static priorities and manual resource monopolies—which often left GPUs idling—and toward a hierarchical budget-based system. Instead of allocating physical machines, management now allocates 'GPU time budgets.' This shifts the conversation from operational troubleshooting to strategic investment; project leads and program managers now decide how to distribute their time shares based on the expected impact of their research.
This system introduces true accountability. Every request for compute must be backed by a budget to avoid preemption. If a researcher attempts to 'squat' on GPUs, they simply burn through their team's allocation without progress. By making resource hoarding expensive, the institution incentivizes researchers to use their allotted time honestly and efficiently, mirroring the way capital is allocated in a business environment.
Implementing Hierarchical Fair-Share
To ensure this budget model translates into actual hardware efficiency, Ai2 implemented a hierarchical fair-share scheduler. The system utilizes a sliding lookback window—defaulting to seven days—to track occupancy. The scheduler automatically prioritizes workloads from teams that have under-utilized their allocations over those that have already reached or exceeded their fair-share limit. This ensures that every research group receives their guaranteed time over the course of a week, even if their specific project workloads are bursty.
The Scheduling Contract
Perhaps the most innovative aspect of the new system is the introduction of a 'scheduling contract.' Long-running AI training jobs, which can span weeks, previously made resource rebalancing nearly impossible. Now, when a workload is submitted, the user must declare a 'minimum runtime'—the duration required to make meaningful progress. During this window, the job is protected from preemption, providing the stability researchers need.
Once that minimum time is reached, the scheduler gains the authority to re-queue the workload to balance the cluster, effectively introducing time-slicing to the infrastructure. This mechanism not only ensures fairness but also allows the system to automate maintenance. If a host requires repairs, the scheduler can naturally drain workloads as they reach their minimum runtime, eliminating the need for manual negotiation with researchers.
Why It Matters
- Maximized Occupancy: The 'unallocated' mode allows researchers to use extra GPU cycles for free, provided their jobs can be preempted at any time, ensuring hardware is never sitting idle.
- Administrative Transparency: By tying compute to budgets, decision-making on project priority is moved into the hands of leadership, reducing the 'on-call' burden on engineers.
- System Resilience: Automated preemption based on the scheduling contract allows for automated maintenance, as the system can safely drain and repair nodes without disrupting long-term training goals.