Democratizing Model Efficiency with Quanto
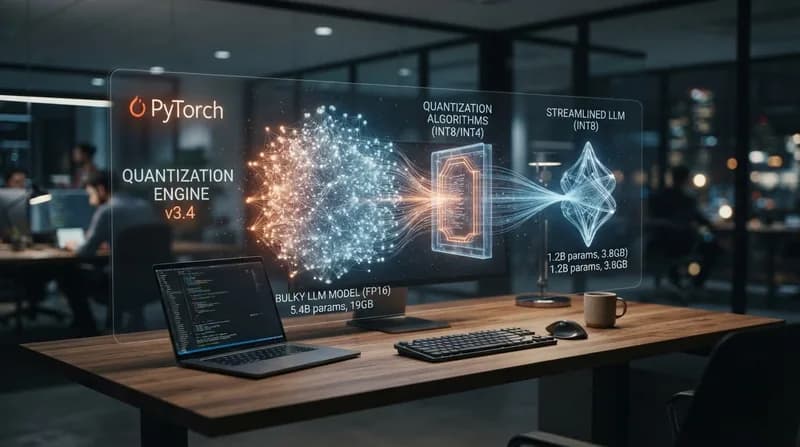
As Large Language Models (LLMs) continue to grow in scale, the challenge of running these complex systems on consumer-grade hardware has become a primary hurdle for developers. Quantization—the process of reducing the precision of a model's weights and activations—is the industry's answer to this footprint problem. However, the ecosystem has long been fragmented by incompatible libraries and hardware-specific restrictions. Enter Quanto, a new PyTorch quantization backend from Hugging Face, designed specifically to bring order and simplicity to this critical workflow.
Unlike many existing solutions that lock users into specific architectures or hardware platforms, Quanto is built for versatility. It operates natively in eager mode, meaning it is compatible with non-traceable models, and provides seamless support for a wide array of devices, including standard CUDA GPUs and Apple Silicon (MPS). By automatically handling the insertion of quantization stubs and functional operations, it lowers the barrier to entry for developers looking to optimize their models for memory and speed.
The Core Quantization Workflow
Quanto simplifies the complex lifecycle of model compression into a handful of manageable steps. The process begins with the conversion of a standard float model into a dynamically quantized state. From there, users have the option to calibrate their models using representative samples to refine activation ranges, ensuring that the model retains its intelligence even after compression. For those requiring even higher precision, Quanto supports Quantization-Aware-Training (QAT), allowing developers to tune the model over a few epochs to regain performance metrics lost during the initial quantization process.
Once the optimization is complete, the final 'freezing' step replaces float weights with their integer counterparts. Hugging Face has prioritized compatibility throughout this lifecycle; the resulting quantized weights are fully compatible with both PyTorch’s standard serialization and the highly efficient Safetensors format, ensuring that developers can easily save and reload their optimized models without breaking compatibility with existing pipelines.
Key Features and Hardware Versatility
The strength of Quanto lies in its technical flexibility and integration capabilities. The library supports a wide range of bit-widths, including int2, int4, int8, and float8 for weights, as well as int8 and float8 for activations. This granularity allows developers to balance accuracy and efficiency depending on the constraints of their target hardware. Furthermore, Quanto is designed to be 'torch.compile' friendly, enabling high-performance inference paths that can be further accelerated through model compilation.
Why it Matters
- Hardware Agnostic: Works across CPU, GPU, and Apple Silicon, breaking the hardware-dependency cycle found in many legacy tools.
- Seamless Integration: Deeply integrated into the Hugging Face Transformers library, allowing for quick deployment using the QuantoConfig class.
- Developer Centric: Provides a streamlined API that manages complex quantization stubs, reducing the boilerplate code traditionally required for model optimization.
- Broad Support: Extends beyond LLMs to support any modality, including audio models like OpenAI's Whisper, proving its value across diverse AI applications.
By providing a unified backend that works consistently across the PyTorch ecosystem, Quanto is poised to become the default choice for developers looking to balance the power of modern AI with the reality of finite computational resources. Whether you are building for edge devices or optimizing server-side throughput, the ability to rapidly cycle between float and quantized models without shifting toolsets marks a significant step forward for the open-source community.