A New Standard for Open-Weight Inference
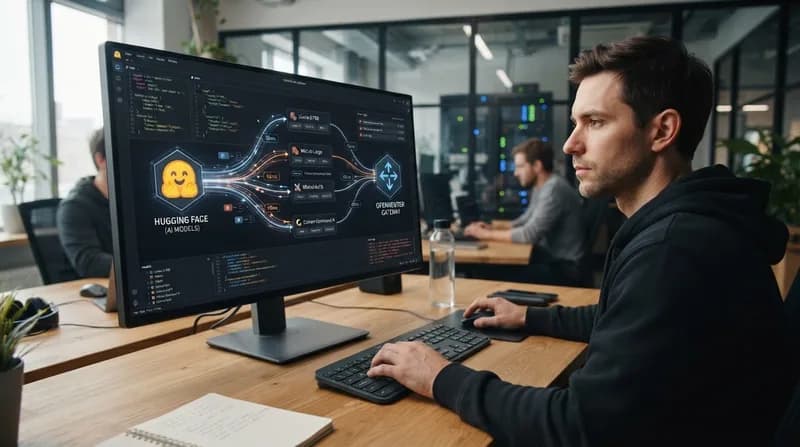
Hugging Face has officially announced a landmark partnership with OpenRouter to streamline how developers interact with open-weight AI models. By replacing its legacy custom routing infrastructure with OpenRouter's sophisticated engine, Hugging Face is now capable of distributing inference requests across more than 80 providers. This integration ensures that every API call is automatically routed to the provider offering the optimal balance of price, speed, and reliability at any given moment.
This strategic move addresses one of the most significant challenges in the open-source AI landscape: fragmentation. By unifying access under a single Hugging Face token, the platform allows developers to utilize their existing codebases while benefiting from an infrastructure that dynamically shifts traffic away from failing or congested providers. This transition maintains API compatibility with industry standards like OpenAI’s Chat Completions and Anthropic’s Messages API, ensuring minimal friction for existing projects.
The Power of Intelligent Routing
The core advantage of this partnership lies in OpenRouter’s ability to conduct real-time performance monitoring. According to recent data, this routing shift has already demonstrated tangible benefits, including a 46% reduction in capacity errors and an approximately 16% improvement in both latency and throughput. When a specific provider encounters performance degradation, the system automatically redirects traffic to a high-performing alternative, often within the same call cycle.
Developers maintain granular control over this process through optional suffixes on model IDs. Users can prioritize specific metrics by appending commands like ":fastest" for raw throughput or ":cheapest" for cost-sensitive operations. Furthermore, the infrastructure is cache-aware; by utilizing a stable UUID in the request headers, developers can ensure that conversation context stays with the provider holding the prompt cache, preventing unnecessary performance overhead.
Why It Matters: Cost and Scale
The shift toward open-weight models is accelerating rapidly. Statistics show that open-weight models now account for the vast majority of tokens served on platforms like OpenRouter, representing a 60-fold increase in weekly volume over the past year. This growth is driven by a clear economic advantage: open-weight models cost, on average, roughly four times less than proprietary closed-model equivalents, while still providing performance that is increasingly competitive on industry-standard benchmarks.
- No Markup Pricing: Hugging Face applies no additional markup to the provider’s base price, maintaining cost transparency.
- Transparency Dashboards: New interface tabs on Hugging Face model pages allow users to view live metrics for every connected provider, including uptime, speed, and cost.
- Customization and Control: Organizations and individual users can blacklist specific providers within their settings, ensuring their traffic never routes to infrastructure that doesn't meet their internal security or compliance requirements.
- Unified Billing: Billing is centralized through Hugging Face, with PRO, Team, and Enterprise plans receiving monthly credits that can be applied toward inference costs.
Future Implications
While proprietary models still lead in top-tier benchmarking performance, the narrowing gap—combined with the massive cost-efficiency of open-weight architectures—suggests that this partnership will be a primary driver for enterprise AI adoption. Future updates are expected to bridge the gap further, allowing users to link their existing OpenRouter accounts directly to Hugging Face and expanding the scope of tasks that benefit from intelligent, cross-provider routing. For developers, the message is clear: the infrastructure supporting open models is becoming as robust and reliable as the closed-source giants they aim to challenge.