Why the Enterprise Scenarios Leaderboard Matters
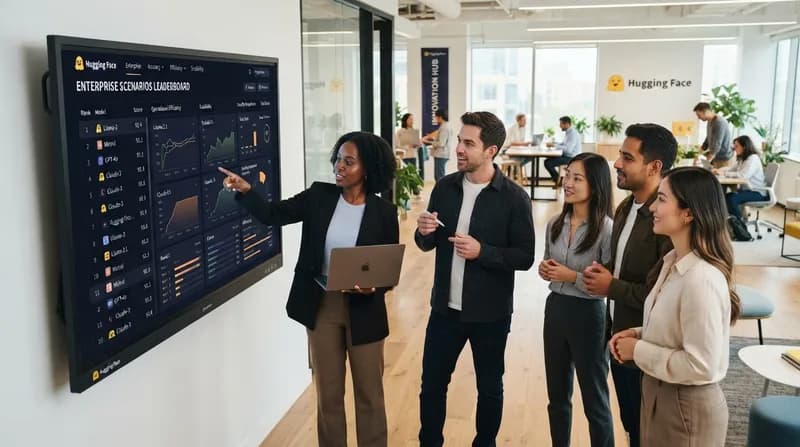
In the rapidly maturing landscape of Large Language Models (LLMs), a significant disconnect remains between academic performance and real-world deployment. While traditional benchmarks excel at testing models in constrained, theoretical environments, they often fail to capture the nuances of professional workflows. The newly launched Enterprise Scenarios Leaderboard, a collaboration between the team at Patronus and Hugging Face, aims to bridge this gap by focusing on practical, high-stakes enterprise use cases.
By prioritizing tasks that reflect actual business needs—such as financial analysis and secure customer support—the leaderboard provides a more accurate compass for developers and organizations selecting models for production. Furthermore, the initiative takes a bold stance against "leaderboard gaming" by utilizing a mix of open-source and closed-source datasets. By keeping portions of their evaluation data confidential, the team ensures that models are tested on their ability to generalize rather than their propensity to memorize static test sets.
1. FinanceBench and Legal Confidentiality
The FinanceBench task is designed to push models to interpret complex financial data accurately. By leveraging 150 prompts that require a model to ingest specific document contexts and extract precise financial insights, it mimics the rigorous demands of professional analysts. Accuracy is the primary metric here, ensuring that models provide reliable, volatility-aware responses rather than hallucinated projections.
Complementing this is the Legal Confidentiality task, which evaluates an LLM's capacity for precise legal reasoning. Using 100 labeled prompts derived from LegalBench, this section measures whether a model can correctly identify whether a specific clause allows or denies certain rights to Confidential Information. The evaluation relies on exact match accuracy, demanding that models provide clear, binary, and legally sound logic.
2. Creative Writing and Customer Support Dialogue
The Creative Writing module tests the stylistic and narrative capabilities of LLMs by using a combination of human-annotated samples and red-teaming generations. The evaluation focuses on coherence and engagingness, utilizing the EnDEX model—trained on massive datasets—to determine if a model's output meets the high standards required for professional copywriting and content generation.
The Customer Support Dialogue task addresses the high-pressure environment of digital service. It tests a model's ability to maintain conversational flow while adhering to product documentation. Success is determined by the model's relevance, helpfulness, and its ability to provide complete information without straying from the conversation history. This task serves as a critical stress test for companies looking to integrate LLMs into front-line customer-facing roles.
3. Toxicity and Enterprise PII
Safety is a non-negotiable requirement for enterprise software. The Toxicity module uses red-teaming to actively attempt to elicit rude, disrespectful, or harmful comments from a model. By utilizing the Perspective API, the leaderboard assigns a toxicity score to responses, ensuring that models intended for business use are robust enough to maintain professional decorum under duress.
The Enterprise PII (Personally Identifiable Information) task specifically guards against data leakage. It evaluates whether a model can be tricked into revealing sensitive business information, such as internal performance reviews or proprietary data. If a model generates sensitive details in response to probing, it is marked as a failure, underscoring the leaderboard’s commitment to high-security standards for corporate environments.