The Illusion of Automated Efficiency
In the modern corporate landscape, the promise of an intelligent Content Management System (CMS) often sounds like a panacea for information overload. By leveraging AI to automate indexing, tagging, and keyword association, organizations hope to eliminate the manual labor of document organization. However, as many IT professionals have discovered, delegating the structure of institutional memory to an unguided or improperly tuned AI model can transform a repository of vital corporate intelligence into a digital graveyard where information goes to vanish.
The fundamental flaw often lies in the reliance on dynamic, nightly tag regeneration. Unlike static, human-curated indices, AI systems that dynamically re-sort content based on fluctuating word frequencies are prone to catastrophic misinterpretation. When an algorithm cannot distinguish between contextually distinct topics—such as confusing "Manila" folders with the city of Manila in the Philippines—the semantic integrity of the entire database begins to crumble. This creates a feedback loop of misinformation, where search results become increasingly irrelevant over time, buried under layers of erroneous metadata.
The "Black Hole" Effect
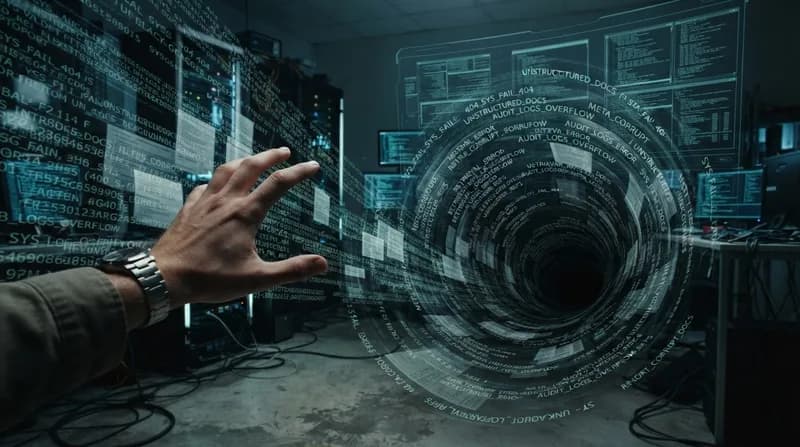
Perhaps the most insidious feature of these systems is their tendency to retain metadata associations even after the primary documents have been deleted or archived. When the AI attempts to force-match orphaned keywords to unrelated files, it creates a labyrinthine environment where simple retrieval requests trigger a cascade of outdated, superseded, or entirely random documentation. For employees, this creates an environment where "finding" a document is a matter of pure chance rather than methodical searching.
This systemic volatility becomes a tool for institutional avoidance. In environments where the CMS acts as a black hole, the act of uploading a document serves as a psychological "completion" of a task, regardless of whether the document is ever retrieved. By effectively ensuring that no one can find the information they need, the system ironically reduces the demand for compliance and review, as the cost of navigating the digital clutter far outweighs the perceived value of the data itself.
Why It Matters
- Loss of Institutional Knowledge: When document versioning becomes a chaotic collection of "pre-drafts" and "cross-amended" files, the organization loses its ability to track the history of its own decisions.
- Algorithmic Over-Correction: Dynamic AI tagging systems that regenerate nightly prevent the development of a stable index, ensuring that search results are perpetually inconsistent.
- The Cost of Poor Procurement: Choosing systems based on superficial features—such as avatar profiles or tag color customization—at the expense of reliable metadata management leads to long-term operational paralysis.
Strategic Implications
The reliance on "all-encompassing" AI keyword association often masks a deeper failure in database architecture. Organizations that treat their CMS as a dumping ground for disparate files, hoping that machine learning will magically impose order, inevitably find themselves trapped in a cycle of forensic data recovery that few employees have the patience or time to navigate. For IT leadership, the lesson is clear: no amount of AI sophistication can substitute for basic principles of data governance, reliable version control, and human-led taxonomy management.