Artificial IntelligenceTechnical Deep Dive

Shrinking the Search: Quantization Revolutionizes Vector Retrieval

Published
EElectricBuzz Editorial Team
Shrinking the Search: Quantization Revolutionizes Vector Retrieval
2 min read253 wordsElectricBuzz Editorial Team

The Gist

“New advancements in binary and scalar embedding quantization are set to drastically reduce the cost and latency of large-scale vector search operations.”

Optimizing Neural Search Efficiency

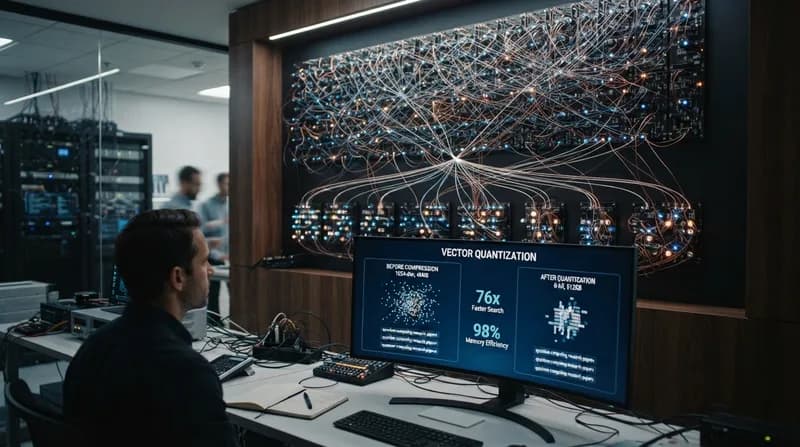
Modern information retrieval systems rely heavily on vector embeddings to map data into high-dimensional spaces. While these embeddings provide remarkable accuracy for semantic search, their sheer size presents a significant hurdle for infrastructure budgets and query latency. The latest breakthrough in embedding quantization offers a solution, enabling developers to compress these vectors into binary or scalar formats without sacrificing meaningful search performance.

By transforming standard dense embeddings into highly compressed representations, systems can now perform similarity lookups orders of magnitude faster. Binary quantization, in particular, reduces the memory footprint of these vectors significantly, allowing for massive indices to fit comfortably in RAM. This transition from 32-bit floating-point numbers to more compact formats effectively lowers the barrier to entry for building lightning-fast RAG (Retrieval-Augmented Generation) pipelines.

Why It Matters

  • Reduced Latency: Compressed vectors allow for faster distance calculations, which is critical for real-time user experiences.
  • Cost Efficiency: By shrinking the memory footprint, organizations can run sophisticated retrieval systems on cheaper, less powerful hardware.
  • Scalability: Smaller indices mean more data can be stored and searched on a single machine, simplifying the architecture for large-scale production applications.

The implementation of these techniques, such as those demonstrated with models like BAAI's bge-large-en-v1.5, showcases a shift in industry priorities toward hardware-efficient AI. By balancing precision with structural efficiency, developers can now deploy high-performing semantic search engines that are both cost-effective and scalable. As the demand for AI-driven retrieval grows, these quantization methods represent a fundamental step toward more sustainable and responsive machine learning infrastructure.
SPONSORED
The 5 Best Over-Ear ANC Headphones of 2026, Tested & Ranked
Editor's Pick Guide
92/100
Tech & Gadgets•12 min read

The 5 Best Over-Ear ANC Headphones of 2026, Tested & Ranked

We locked five over-ear ANC picks for 2026 — Sony WH-1000XM6, Bose QuietComfort Ultra 2, Soundcore Space One, Sennheiser Momentum 5, and Apple AirPods Max 2 — then stress-tested them on lab metrics, long-term owner truth, and live street prices.

Related Stories

Semantically matched articles, ranked by topic overlap and freshness.

Stepping Into the Chaos: A Digital Re-Creation of the Theranos Era
Artificial Intelligence

Stepping Into the Chaos: A Digital Re-Creation of the Theranos Era

A new interactive website offers a hyper-realistic simulation of Elizabeth Holmes' office, allowing users to explore actual evidence from the infamous Theranos trial through a vintage digital lens.

Bridging the Enterprise Gap: Snorkel AI Integrates Hugging Face to Tame Foundation Models
Artificial Intelligence

Bridging the Enterprise Gap: Snorkel AI Integrates Hugging Face to Tame Foundation Models

A powerful collaboration between Snorkel AI and Hugging Face is streamlining the path for enterprises to fine-tune and deploy open-source foundation models with unprecedented efficiency.

Hollywood’s New Tech Mogul: Why Ben Affleck’s Deep Dive into AI is Captivating the Industry
Artificial Intelligence

Hollywood’s New Tech Mogul: Why Ben Affleck’s Deep Dive into AI is Captivating the Industry

Ben Affleck has stepped beyond the silver screen to showcase a sophisticated understanding of neural networks, machine learning, and the future of AI-driven cinema.

Unlocking Federated Learning: The Substra-Hugging Face Collaboration
Artificial Intelligence

Unlocking Federated Learning: The Substra-Hugging Face Collaboration

Hugging Face and Owkin are bridging the gap between high-performance AI and data privacy through the integration of the Substra framework.

Bridging the Gap: Why OpenAI’s Latest Math Proofs Are Facing Skepticism
Artificial Intelligence

Bridging the Gap: Why OpenAI’s Latest Math Proofs Are Facing Skepticism

OpenAI’s recent release of high-level mathematical solutions is drawing fire from the academic community for failing to meet formal rigorous standards and human-centric transparency.

Anthropic Overhauls Usage Policy to Curb Model Abuse and Election Interference
Artificial Intelligence

Anthropic Overhauls Usage Policy to Curb Model Abuse and Election Interference

Anthropic has implemented a sweeping update to its acceptable use policy, explicitly banning abusive interactions with its AI models and introducing strict safeguards against election manipulation.

JPMorgan Retains Crown as Global Leader in AI Banking Integration
Artificial Intelligence

JPMorgan Retains Crown as Global Leader in AI Banking Integration

New data from Evident Insight confirms that JPMorgan Chase remains at the forefront of the financial sector's aggressive artificial intelligence transformation.

Mastering Graph Classification with Transformer Models
Artificial Intelligence

Mastering Graph Classification with Transformer Models

Hugging Face’s implementation of Microsoft’s Graphormer brings powerful transformer-based architecture to graph machine learning tasks.