The Era of On-Device Intelligence
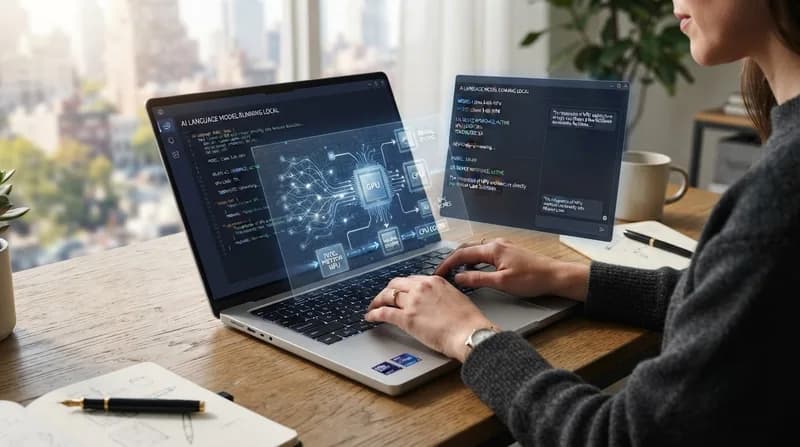
The push to move artificial intelligence away from massive data centers and directly onto personal hardware is accelerating. Recent benchmarks and technical integration efforts have demonstrated that high-performing, compact Large Language Models (LLMs) can run effectively on standard consumer hardware. By leveraging the unique architectural benefits of Intel's Meteor Lake processors—specifically their integrated NPU (Neural Processing Unit)—developers are achieving impressive inferencing speeds for models once thought to be too demanding for laptops.
The focus has shifted toward models like Microsoft’s Phi-2 and the TinyLlama series. These compact models, featuring parameters in the 1B to 3B range, offer a compelling balance between conversational fluency and computational efficiency. By optimizing these models to run natively on the CPU and NPU architecture within the Meteor Lake chip, users can maintain privacy and operate AI assistants without an active internet connection, significantly reducing latency compared to cloud-based alternatives.
Why This Matters for Consumers
- Offline Capability: Eliminates reliance on server connectivity, ensuring privacy and reliability in remote environments.
- Optimized Power Draw: The NPU offloads AI workloads from the CPU, preserving battery life for mobile computing.
- Low Latency: Local execution enables instantaneous response times, vital for real-time document analysis and coding assistance.
This development signals a major shift in how we conceive of 'smart' devices. Instead of requiring a beefy GPU or high-speed cloud access, the next generation of laptops will feature hardware designed specifically to accelerate transformer-based architectures. As these optimizations become more widespread, we can expect local AI to transition from a niche developer interest to a standard feature for productivity tools, enabling sophisticated text generation and reasoning capabilities right out of the box.