The Vulnerability of Unicode in Navigation
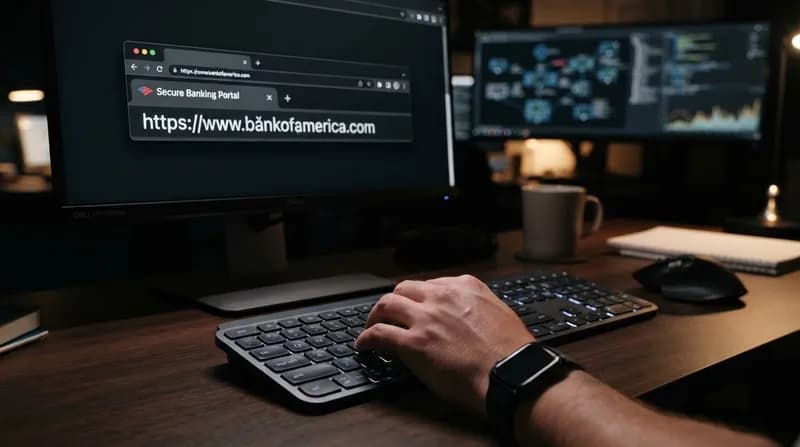
As web browsers evolve, they increasingly support Internationalized Domain Names (IDNs) to accommodate global users. However, this flexibility creates a persistent security challenge: typosquatting. Cyber-imposters have long utilized visually similar characters to trick users into visiting fraudulent sites. A new report from the researchers at Have I Been Squatted highlights how two specific characters—the Cyrillic character ө and the Latin 'k with hook' (ƙ)—can successfully bypass the built-in defenses of major Chromium-based browsers, including Chrome and Edge.
These characters act as 'breakers,' a term used for symbols that do not appear on browser manufacturers' hardcoded lists of known Cyrillic or non-ASCII lookalikes. By inserting these symbols into domain names, attackers can register sites that look identical to legitimate brands when rendered in Unicode, while avoiding the browser's safety mechanisms that would normally force a display of the underlying, less-deceptive Punycode.
How the Chromium Security Layers Are Bypassed
Chromium-based browsers rely on two primary defense mechanisms, both of which face limitations when confronted with these specific glyphs. The first is the SafeToDisplayAsUnicode function, which executes a series of seven checks to detect common spoofing patterns. Crucially, these checks are designed to trigger only if a domain name contains a uniform set of characters from a blacklist. Because the 'breaker' characters used by the researchers are not on the list, the browser fails to recognize the domain as an unsafe spoofing attempt, permitting it to be displayed as a standard Unicode address.
The second layer of defense involves the GetSimilarTopDomain() function. This system generates a 'skeleton' of the URL by removing diacritics and simplifying characters to see if the resulting string matches a database of nearly 8,500 popular websites. The researchers found that the Latin 'ƙ' and the Cyrillic 'ө' possess unique properties—such as adding a combining mark to the skeleton rather than being stripped—which causes the domain to deviate from the known list. As a result, the browser concludes the domain is unique and safe, failing to trigger the necessary security warnings for the user.
The Limits of Safety Tips
In addition to these underlying checks, browsers use 'Safety Tips'—pop-up warnings that notify users when they are navigating to a suspicious site. However, these alerts possess rigid parameters that limit their effectiveness. The warnings only appear for domains that are an exact-character match, a one-edit match, or a site involving an adjacent character swap from a legitimate URL. Furthermore, domains with fewer than five characters, such as the spoofed version of 'Okta' created by the team, often slip through these protections entirely.
The researchers conducted a comprehensive analysis of the 167 million currently registered .com domains to understand the potential scope of this issue. They discovered approximately 162,000 pairs of domains where an IDN closely resembles a standard ASCII-based URL. While many of these are likely registered by organizations for defensive purposes or international branding, the findings serve as a stark reminder that browser-side defenses are not infallible. As attackers continue to find new ways to exploit the quirks of international character sets, security experts suggest that organizations must proactively monitor domain registrations to protect their digital footprint.