Efficiency Through Nested Dimensions
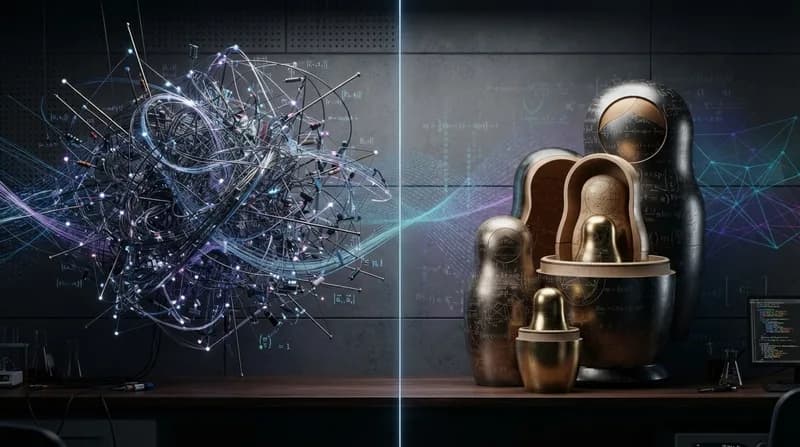
The landscape of vector search and information retrieval is shifting as Hugging Face introduces Matryoshka Embedding Models. Unlike traditional embedding architectures that output a fixed, rigid dimension size, these models are designed to store information in a nested structure—much like the iconic Russian dolls from which they draw their name. By structuring data this way, developers can effectively truncate embeddings without sacrificing significant semantic accuracy, allowing for massive performance optimizations.
This breakthrough is particularly critical for large-scale applications where latency and storage costs are major bottlenecks. By training models to accommodate varying precision levels, the system allows for an adaptive search process. A user can start with a smaller, highly compressed vector for an initial, fast-pass scan of a database, and then selectively upscale to a larger, higher-resolution version of that same embedding for a more precise re-ranking of results.
Why it Matters
- Storage Optimization: Significantly reduces the disk space required for vector databases.
- Latency Reduction: Enables faster retrieval by processing smaller data footprints during initial search stages.
- Adaptive Accuracy: Provides the flexibility to balance computational costs against the need for extreme precision in retrieval tasks.
- Seamless Integration: Compatible with existing infrastructure, making it easier for developers to deploy high-performance search systems.
The introduction of the Microsoft mpnet-base variant, which clocks in at 0.1B parameters, demonstrates that this efficiency isn't limited to experimental labs. It offers a practical path forward for production environments looking to scale their AI agents or search platforms. By adopting this nested approach, organizations can maintain state-of-the-art performance while minimizing the infrastructure overhead that usually accompanies high-dimensional vector modeling. As AI search becomes more ubiquitous, tools that prioritize efficiency without compromising the integrity of data representation will likely become the industry standard for next-generation retrieval systems.