The Exchange Admin Center Incident
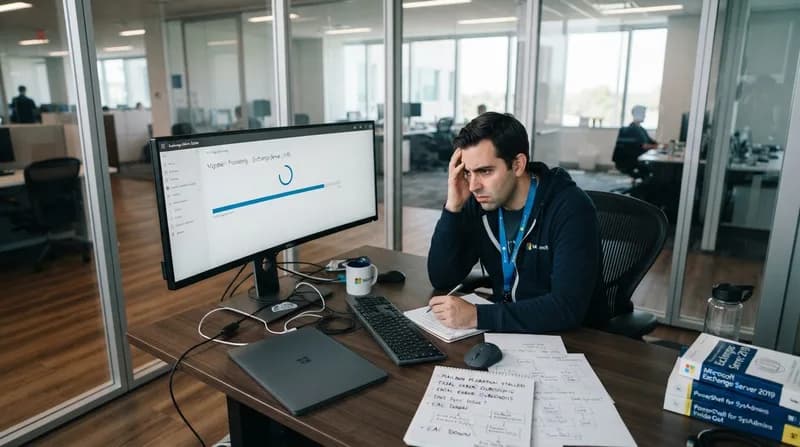
Earlier this week, administrators managing Microsoft’s Exchange Online ecosystem found themselves staring at persistent 'Internal Server Error' screens. The outage, which primarily affected the web-based Exchange Admin Center (EAC), rendered IT professionals unable to manage critical mailboxes, groups, or organizational policies. The disruption began mid-morning, with Microsoft eventually acknowledging that unexpected 302 redirect errors were triggering the failures across the board.
For those unfamiliar with the platform, the EAC serves as the primary command center for modern Microsoft 365 environments. Because the console is designed to mirror the broader M365 administrative experience, its failure effectively blinded admins to their own infrastructure. With no documented workarounds available during the outage, the incident forced a period of total inactivity for those relying on the dashboard for essential daily operations.
The Root Cause: Configuration Slip-ups
Microsoft attributed the service collapse to a specific configuration change that was rolled out to the production environment. According to the company's technical updates, this change introduced unexpected HTTP responses that obstructed the request path for users. The fix, while swift in its execution, was relatively rudimentary: engineers simply reverted the configuration to its previous state. Once the rollback was finalized, service functionality returned to normal.
This event follows a recurring pattern of 'service wobbles' within the Microsoft ecosystem. Whether it is issues with SharePoint Online accessibility or authentication hiccups in mobile applications like Outlook for iOS, internal configuration errors have become a chronic pain point. While Microsoft has promised a formal Post-Incident Report and a review of their telemetry to better detect these patterns, the frequency of such incidents has led many in the sysadmin community to demand more rigorous pre-deployment testing strategies.
Why It Matters
- Systemic Fragility: These recurring outages suggest that despite high levels of automation, the deployment pipeline for cloud services remains vulnerable to human-led configuration errors.
- Operational Downtime: When the central hub for M365 management goes dark, businesses lose the agility to manage security, user access, and mail flow, creating a significant productivity bottleneck.
- The Testing Question: As IT departments rely more on integrated AI-assisted development tools, there is growing scrutiny regarding how much validation is actually being performed before a live rollout occurs.
The company has pledged to improve its monitoring systems, but for many organizations, the primary hope remains that future updates will prioritize stability over the rapid iteration cycles that have increasingly led to these high-profile disruptions.