Democratizing Large Language Models
The landscape of artificial intelligence is defined by the sheer scale of modern large language models (LLMs). While these models exhibit remarkable performance in natural language processing, their deployment has historically been gatekept by the massive computational requirements demanded of hardware. Hugging Face is shifting this paradigm, aiming to make state-of-the-art machine learning accessible to a wider audience through the official integration of the AutoGPTQ library directly into its Transformers framework.
By utilizing the GPTQ algorithm, this update allows developers and researchers to quantize models into 8, 4, 3, or even 2-bit precision. This significant reduction in bit-depth enables complex models that once required enterprise-grade server clusters to run on much more modest, consumer-level hardware. The process effectively bridges the gap between massive theoretical performance and practical, real-world utility.
The Mechanics of GPTQ Quantization
GPTQ, or Generalized Post-Training Quantization, serves as an efficient method for compressing weight-heavy models. Unlike other approaches that may necessitate extensive retraining, GPTQ operates as a post-training technique, utilizing a calibration dataset to minimize the mean squared error during compression. This method employs a mixed int4/fp16 scheme, where model weights are stored in 4-bit integers while activations remain in 16-bit floating point format during actual computation.
The primary advantage of this architecture is a massive reduction in memory consumption—often cutting requirements by up to four times. Because the dequantization of weights occurs directly within the GPU kernel near the compute unit, rather than in global memory, users experience significant speedups without a noticeable degradation in accuracy. This efficiency makes it feasible to run models that would otherwise exceed the memory overhead of a single GPU.
Seamless Integration and Expanded Capabilities
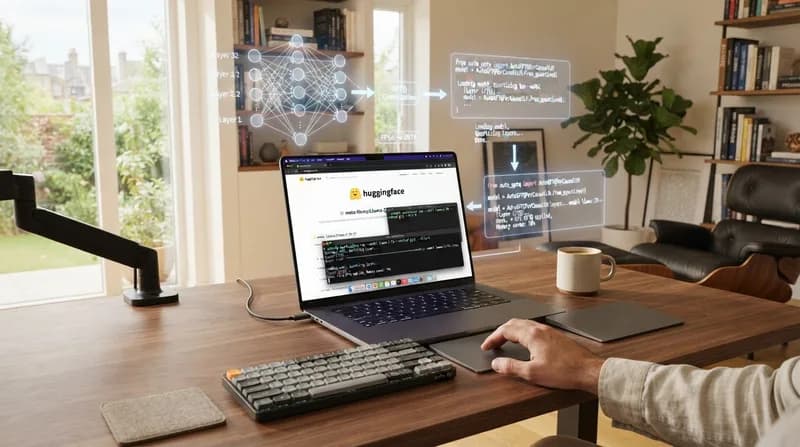
The inclusion of AutoGPTQ within the Hugging Face Transformers ecosystem is designed for immediate developer adoption. By leveraging the Optimum library, users can quantize their own models with just a few lines of code or utilize pre-quantized models already available on the Hugging Face Hub. The integration features native support for both Nvidia CUDA kernels and RoCm-powered AMD GPUs, broadening the hardware compatibility spectrum.
Beyond basic inference, the system supports fine-tuning through the PEFT (Parameter-Efficient Fine-Tuning) library. By freezing the core layers of a quantized model and applying trainable adapters, researchers can continue to specialize their models for specific domains without needing the massive resources required for a full-model fine-tune. Furthermore, support has been extended to the Text-Generation-Inference (TGI) library, enabling production-ready deployment of massive models, such as 70B parameter iterations, on single-GPU configurations.
Outlook and Future Implications
While the current AutoGPTQ integration marks a significant milestone for LLM accessibility, the ecosystem remains ripe for further innovation. Future developments are likely to focus on the optimization of custom kernels, particularly the development of high-performance W4A16 kernels written in Triton. Additionally, the industry is already looking toward more advanced quantization schemes, such as those that compress both weights and the key-value cache simultaneously.
As these tools continue to mature, the barrier to entry for fine-tuning and running sophisticated AI agents will continue to drop. This evolution ensures that the next generation of AI development will not be limited to those with the deepest pockets for compute, but rather to those with the most creative applications for the technology.