Measuring the State of Synthetic Speech
Hugging Face is shaking up the landscape of generative audio with the launch of the TTS Arena, a new platform dedicated to benchmarking text-to-speech (TTS) models. As synthetic voice technology rapidly evolves, developers and researchers have struggled to find a standardized way to compare the naturalness, clarity, and emotional range of different AI models. By leveraging the power of community-driven blind testing, the TTS Arena aims to establish a definitive leaderboard for high-fidelity speech synthesis.
Why it Matters
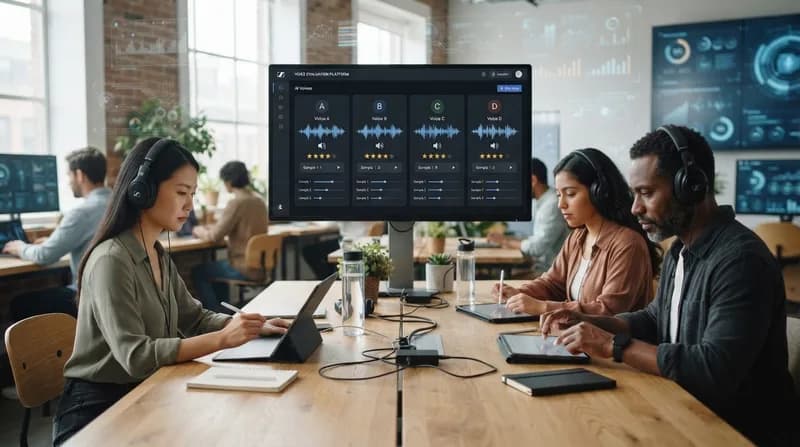
- Blind Evaluation: Users compare outputs from competing models without knowing the source, eliminating brand bias and focus on raw audio quality.
- Dynamic Ranking: The leaderboard updates in real-time based on community votes, reflecting the current state-of-the-art developments in the field.
- Transparency: It provides a clear view of which architectures are winning the "human-like" test, guiding developers toward more effective training methodologies.
The platform functions similarly to other popular model arenas, presenting users with audio samples and asking them to identify the superior output. This iterative feedback loop is essential for pushing the boundaries of prosody and articulation, areas where current AI often falters. By creating this testing ground, Hugging Face is fostering a more competitive ecosystem where quality is driven by direct listener experience rather than theoretical metrics alone.
As the industry moves toward more sophisticated AI agents capable of seamless verbal interaction, the role of the TTS Arena becomes even more critical. Ensuring that synthetic voices are indistinguishable from human speakers is a fundamental step in making AI assistants more approachable and effective for everyday consumer use. With the transition to TTS Arena V2 now active, the platform is poised to become the industry-standard benchmark for the next generation of voice-based artificial intelligence.