Quantifying Model Safety
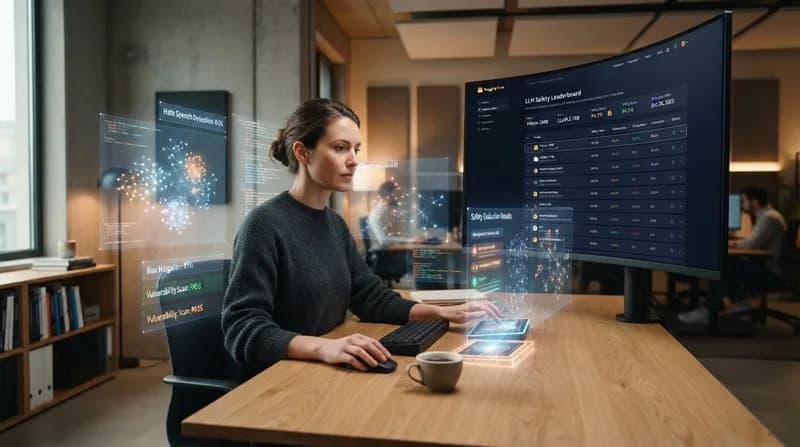
Hugging Face has officially expanded its evaluation ecosystem with the launch of the AI Secure LLM Safety Leaderboard. As the industry grapples with the rapid proliferation of foundation models, this new platform provides a centralized, transparent hub for tracking the robustness and security posture of various AI architectures. By shifting the focus from purely creative or logic-based performance to safety benchmarks, the project aims to establish standardized metrics for trust and reliability.
Why It Matters
The rise of LLMs has brought concerns regarding adversarial attacks, data poisoning, and potential security vulnerabilities to the forefront of AI development. Historically, evaluating safety was fragmented across isolated research papers and proprietary tests. This leaderboard aggregates performance data from diverse models, allowing researchers and developers to compare how different systems handle security-critical scenarios. It is a vital step toward creating a safer, more predictable landscape for deploying enterprise-grade AI.
Platform Capabilities
The leaderboard platform is designed for agility and community-driven verification. Users can browse existing performance metrics, filter by model architecture, and submit their own benchmark evaluations. The system also supports advanced features like CPU-based testing agents, ensuring that even developers with limited access to specialized high-end hardware can contribute to the safety assessment process. By facilitating a more collaborative evaluation framework, Hugging Face is positioning this tool as an essential utility for anyone committed to the responsible release of large language models. The integration into the wider Hugging Face suite means that safety data is now as accessible as model weights and datasets, making security a primary, rather than peripheral, concern in the development pipeline.