Revolutionizing Embedding Performance
The landscape of large language model (LLM) embeddings is shifting as researchers uncover smarter ways to process token representations. A new development, featured in the latest update from the open-source community, introduces token pooling-aware training for multi-vector embedding models. This approach addresses the common bottleneck of how high-dimensional semantic data is compressed into a fixed representation, a challenge that has long limited the fidelity of information retrieval tasks.
The Core Methodology
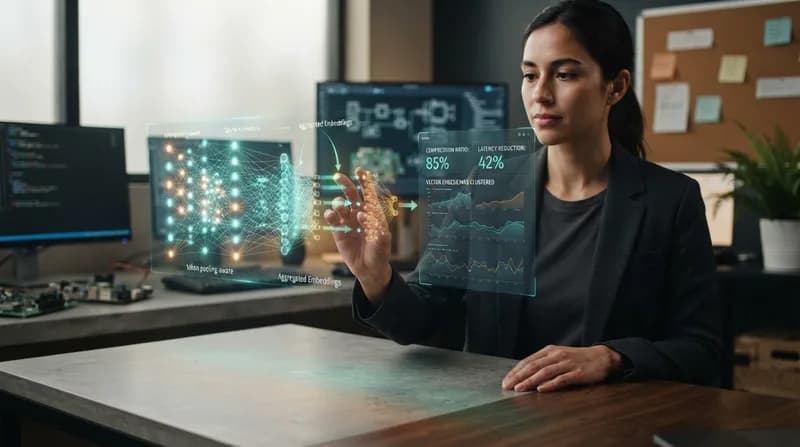
At its heart, this strategy focuses on how models handle the "pooling" phase—the process of distilling multiple token vectors into a single coherent vector for search or classification. Traditional models often perform this pooling after training is complete, treating it as an afterthought. By contrast, token pooling-aware training ensures the model learns the optimal representation specifically for the intended pooling mechanism during the training phase itself. This tighter integration minimizes information loss and forces the architecture to prioritize the most semantically relevant features from the start.
Why It Matters
- Enhanced Semantic Fidelity: By training the model to anticipate how tokens will be pooled, the resulting embeddings are more robust for downstream retrieval tasks.
- Architecture Efficiency: This method allows for more compact embedding vectors without sacrificing accuracy, leading to faster lookups.
- Model Flexibility: Developers can now deploy models like ModernBERT that are specifically tuned for these pooling operations, bridging the gap between raw token output and usable data.
As AI applications scale, the need for efficient, high-accuracy embedding extraction is paramount. This advancement underscores a broader shift in AI development toward optimizing the foundational layers of information processing. By refining how models synthesize complex token relationships, developers can significantly reduce the computational cost of RAG (Retrieval-Augmented Generation) systems while simultaneously improving response quality. It is a subtle but critical step forward in the quest for more effective language comprehension at scale.