Artificial IntelligenceTechnical Deep Dive

Scaling Intelligence: Navigating Distributed Training from PyTorch DDP to Hugging Face Accelerate

Published
EElectricBuzz Editorial Team
Scaling Intelligence: Navigating Distributed Training from PyTorch DDP to Hugging Face Accelerate
3 min read485 wordsElectricBuzz Editorial Team

The Gist

“Moving from single-GPU training to distributed environments can be complex, but three distinct levels of abstraction—native PyTorch, Accelerate, and the Trainer API—offer a streamlined path forward for modern AI development.”

Native PyTorch Distributed Data Parallelism (DDP)

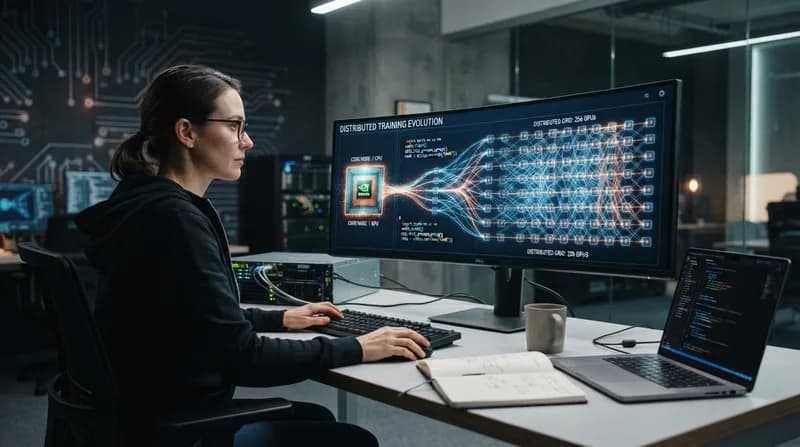
For many developers, the journey into distributed computing begins with the torch.distributed module. Native DDP allows for the training of models across multiple GPUs or even across multiple machines. However, this approach requires significant boilerplate code. To implement DDP, developers must manually define a setup function that establishes a process group, specifying the master address and port for inter-process communication. This creates the environment where individual GPU ranks can synchronize their gradients.

The core of DDP is the DistributedDataParallel wrapper. When applied, it automatically handles the replication of the model across devices. During backpropagation, the module performs an all-reduce operation, averaging the gradients across all copies of the model. While powerful, this manual orchestration requires the developer to manage device IDs and ensure the optimizer is correctly initialized for the specific GPU rank, making it a granular but labor-intensive process.

Scaling with Hugging Face Accelerate

To move beyond the complexities of native DDP, Hugging Face introduced Accelerate. This library acts as a sophisticated wrapper that abstracts away the underlying complexities of hardware management. The primary advantage here is code portability; the same training logic can run seamlessly on a single GPU, multiple GPUs, or TPUs without requiring extensive modifications. By utilizing an Accelerator object, the library takes responsibility for model, optimizer, and DataLoader placement.

Beyond just ease of use, Accelerate improves resource efficiency through optimized data loading. Unlike native DDP, which may inadvertently replicate datasets across memory, Accelerate employs custom samplers. These distribute subsets of data across devices, ensuring only necessary segments occupy memory. This architecture allows developers to tackle significantly larger datasets without triggering memory overflows, effectively democratizing access to high-performance distributed training.

The Trainer API: Maximum Abstraction

For those looking to focus entirely on model architecture and evaluation rather than the intricacies of training loops, the high-level Trainer API provides the ultimate abstraction layer. It encapsulates the repetitive boilerplate code—such as gradient updates, logging, and evaluation cycles—into a single, cohesive interface. This high-level approach supports various hardware configurations out of the box, allowing researchers and engineers to pivot between distributed scenarios with minimal friction.

Additionally, for developers working within interactive environments, Accelerate offers the notebook_launcher. This utility solves the long-standing challenge of running distributed training directly from a Jupyter Notebook. By simply passing the training function and the desired number of processes to the launcher, developers can harness multi-GPU or TPU acceleration without leaving their preferred prototyping environment, effectively closing the gap between research experiments and full-scale distributed training.

Why It Matters

  • Efficiency: Distributed training drastically reduces the time required to train large-scale neural networks.
  • Portability: By using wrappers like Accelerate, code becomes hardware-agnostic, reducing tech debt.
  • Scalability: Optimized data samplers enable the handling of datasets that far exceed the memory capacity of a single GPU.
  • Workflow: Tools like the notebook_launcher lower the barrier to entry for performing complex, multi-device tasks within standard development workflows.
SPONSORED
The 5 Best Over-Ear ANC Headphones of 2026, Tested & Ranked
Editor's Pick Guide
92/100
Tech & Gadgets•12 min read

The 5 Best Over-Ear ANC Headphones of 2026, Tested & Ranked

We locked five over-ear ANC picks for 2026 — Sony WH-1000XM6, Bose QuietComfort Ultra 2, Soundcore Space One, Sennheiser Momentum 5, and Apple AirPods Max 2 — then stress-tested them on lab metrics, long-term owner truth, and live street prices.

Related Stories

Semantically matched articles, ranked by topic overlap and freshness.

Unlocking Efficiency: How BigScience Optimized Large-Scale LLM Inference
Artificial Intelligence

Unlocking Efficiency: How BigScience Optimized Large-Scale LLM Inference

Hugging Face and the BigScience initiative are tackling the heavy compute demands of large language models through smarter inference optimization strategies.

Hugging Face Brings Stable Diffusion to the JAX Ecosystem
Artificial Intelligence

Hugging Face Brings Stable Diffusion to the JAX Ecosystem

Stable Diffusion is getting a performance boost as Hugging Face introduces support for Google’s JAX and Flax frameworks.

Stack Overflow Scales Agentic Future With OpenAI Integration
Artificial Intelligence

Stack Overflow Scales Agentic Future With OpenAI Integration

By leveraging OpenAI's Codex and a new ChatGPT plugin, Stack Overflow has supercharged its agent development pipeline and seen registration numbers skyrocket.

Empowering Finance: How Benefit Street Partners Leverages AI to Modernize Investment Analysis
Artificial Intelligence

Empowering Finance: How Benefit Street Partners Leverages AI to Modernize Investment Analysis

Benefit Street Partners has transformed its investment workflow by utilizing OpenAI’s Codex to build proprietary tools that accelerate loan valuation tracking and complex credit agreement analysis.

Replit Shifts Strategic Focus, Naming OpenAI as Primary AI Partner
Artificial Intelligence

Replit Shifts Strategic Focus, Naming OpenAI as Primary AI Partner

Replit has officially pivoted its default model provider from Anthropic to OpenAI, citing significant gains in performance, cost-efficiency, and partnership synergy for its AI coding agents.

Hugging Face Inference Endpoints: Simplifying ML Production Deployments
Artificial Intelligence

Hugging Face Inference Endpoints: Simplifying ML Production Deployments

Hugging Face is streamlining the transition from model training to production with its Inference Endpoints service, designed to remove the traditional hurdles of infrastructure management.

Mastering Personalization: Fine-Tuning Stable Diffusion via DreamBooth
Artificial Intelligence

Mastering Personalization: Fine-Tuning Stable Diffusion via DreamBooth

Hugging Face is streamlining AI customization, allowing users to inject specific subjects into Stable Diffusion models through the DreamBooth technique.

Unlocking Semantic Search: The Power of MTEB
Artificial Intelligence

Unlocking Semantic Search: The Power of MTEB

A deep dive into the Massive Text Embedding Benchmark, the industry standard shaping the future of how AI models understand human language.